Self-Improvement Configuration
Keys of the [evaluator] block and the commands around it. For the idea, read Self-Improvement; for the walkthrough, the guide Help Pando learn from your sessions.
Web UI: Settings > Self-Improvement. Also available in the TUI settings.
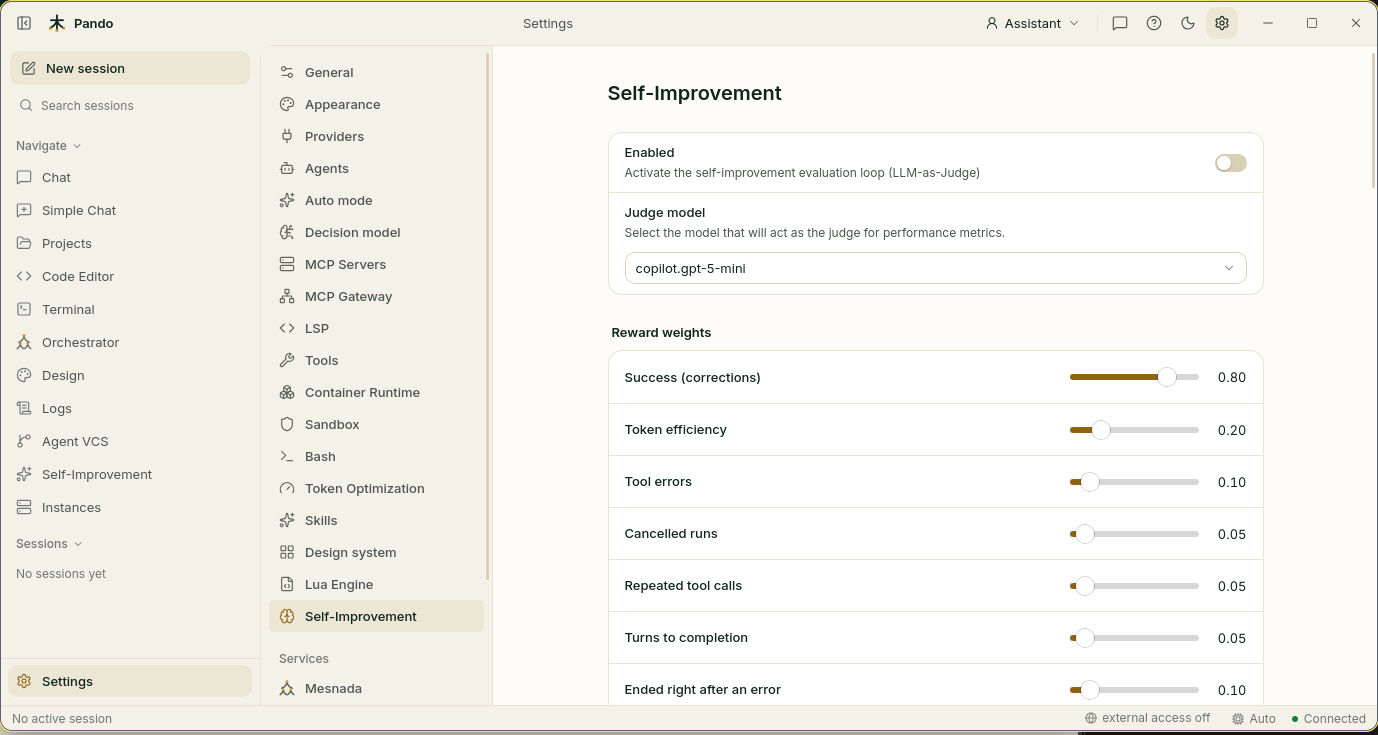
Main keys
[evaluator]
enabled = true
model = 'anthropic.claude-haiku-4'   # the judge; a cheap model is enough
provider = ''
async = true                 # evaluate in the background
idleTimeout = '30m'          # score a session after this long without activity
backfillLimit = 50           # old unscored sessions evaluated at startup; negative disables
backfillJudge = false        # also run the judge on those
includeSubagents = false     # also score delegated (child) sessions
explorationC = 1.41
minSessionsForUCB = 5
maxTokensBaseline = 50
maxSkills = 100
judgePromptTemplate = ''     # path to a custom .md or .txt Go template
correctionsPatterns = []     # regex list; empty = built-in patterns

[evaluator.judge]
highReward = 0.8             # the judge runs at or above this reward…
lowReward = 0.3              # …or at or below this one
minTurns = 4                 # minimum user turns
maxTranscriptTokens = 6000   # head and tail of the transcript kept
dailyCalls  = 20             # judge calls per local day; 0 = no limit
dailyTokens = 200000         # judge tokens per local day; 0 = no limit

[evaluator.templates]
enabled = true # prompt variant selection; inert until variant files exist| Key | Default | Web UI label |
|---|---|---|
enabled | false | Enabled |
model | none | Judge model |
async | true | Async evaluation |
idleTimeout | 30m | Idle timeout |
backfillLimit | 50 | Backfill limit |
backfillJudge | false | Judge during backfill |
includeSubagents | false | Include subagent sessions |
explorationC | 1.41 | UCB exploration factor |
judgePromptTemplate | built-in | Judge prompt template |
correctionsPatterns | built-in | Correction patterns |
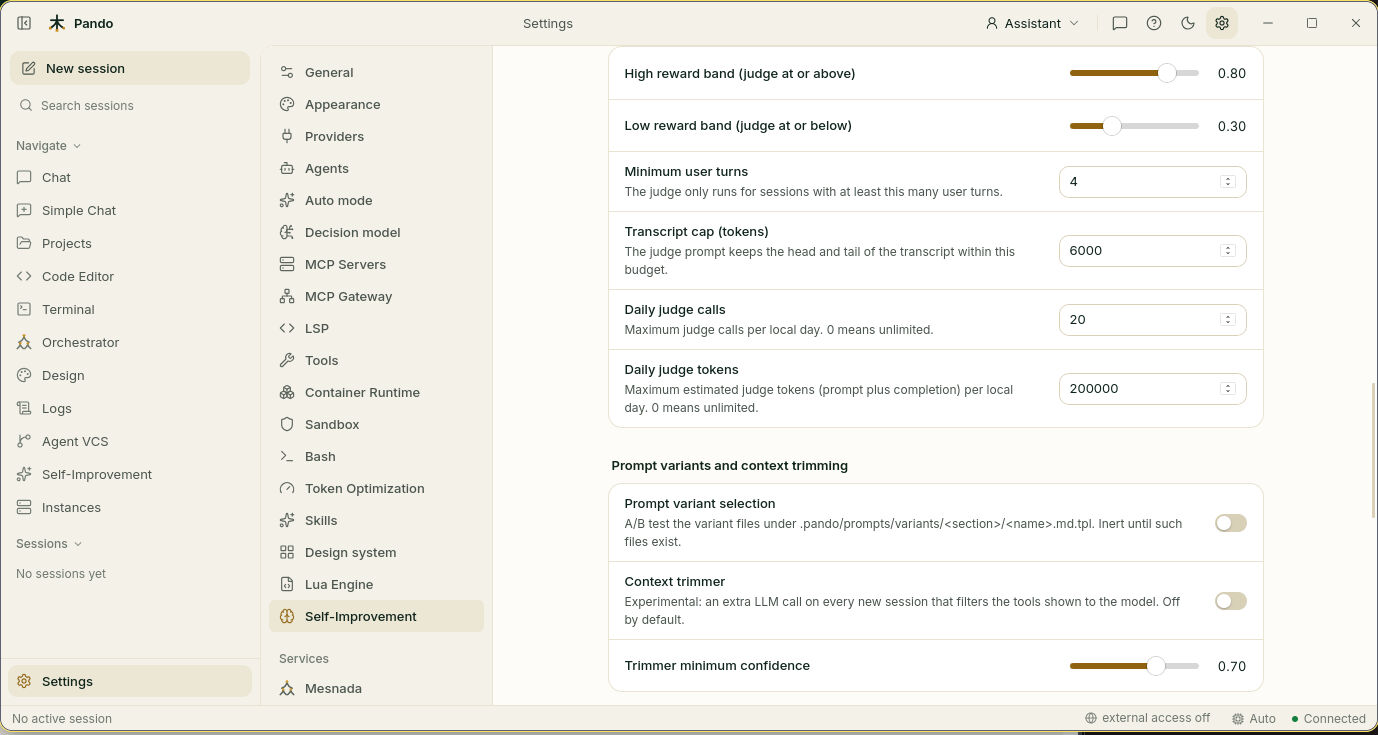
judge.highReward | 0.8 | High reward band (judge at or above) |
judge.lowReward | 0.3 | Low reward band (judge at or below) |
judge.minTurns | 4 | Minimum user turns |
judge.maxTranscriptTokens | 6000 | Transcript cap (tokens) |
judge.dailyCalls | 20 | Daily judge calls |
judge.dailyTokens | 200000 | Daily judge tokens |
templates.enabled | true | Prompt variant selection |
minSessionsForUCB | 5 | |
maxTokensBaseline | 50 | |
maxSkills | 100 |
Reward weights
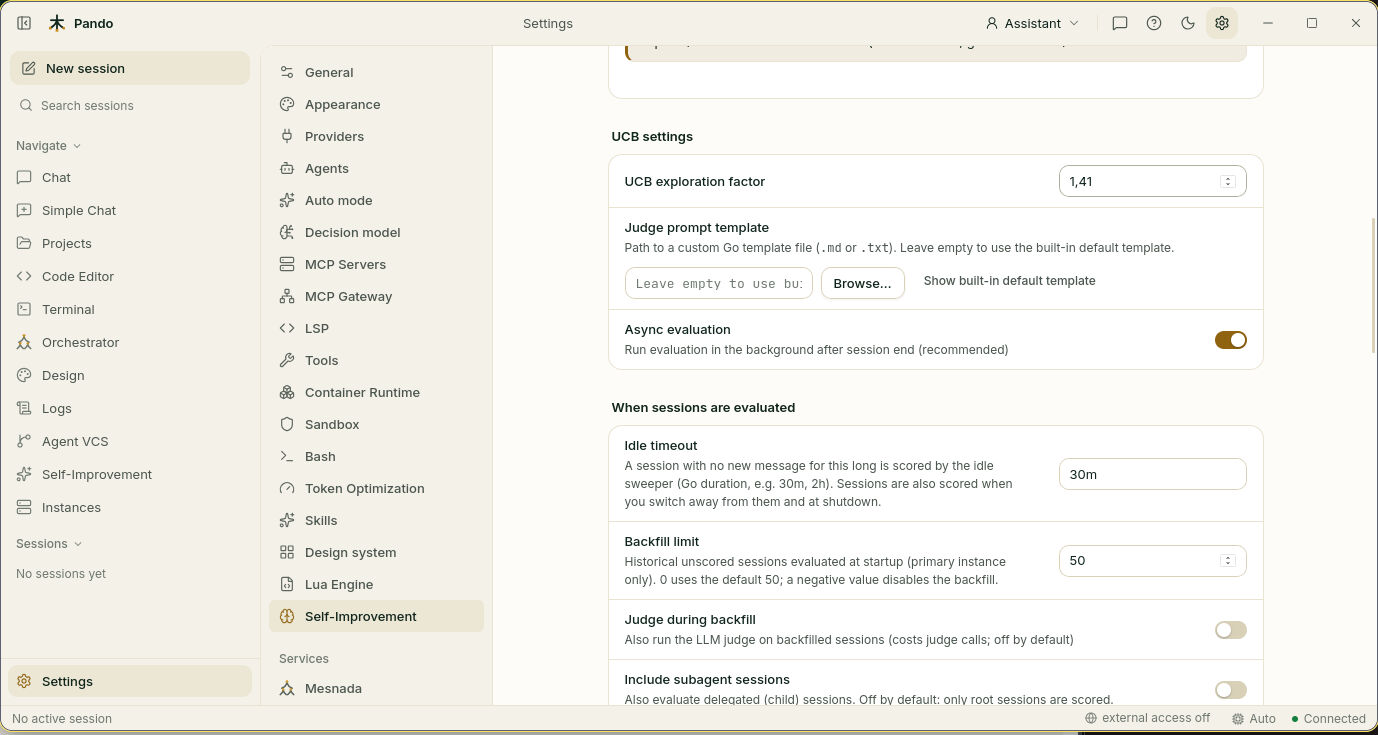
The reward is the weighted mean of the signals measured for each session. Weights are relative. Web UI sliders and starting values: Success (corrections) 0.80, Token efficiency 0.20, Tool errors 0.10, Cancelled runs 0.05, Repeated tool calls 0.05, Turns to completion 0.05, Ended right after an error 0.10. In the config file they live under [evaluator.weights]; the older alphaWeight (success, 0.8) and betaWeight (token efficiency, 0.2) keys are still read when no weights are set.
Explicit /feedback overrides the total: bad below 0.3, good above 0.8.
When a session is scored
- When you switch away from it.
- After
idleTimeoutwithout a new message. - At shutdown.
- By the startup backfill (primary instance only), up to
backfillLimitsessions.
Scoring calls no model. The judge model is called only for sessions inside the reward bands, with at least minTurns user turns, and within the daily budget.
Learned skills
The judge’s proposals are files under .pando/skills/learned/<id>.md with status pending. Only approved skills are injected into prompts, and an approval reaches the next new session, never one in progress. Rejected skills are never injected and never proposed again.
pando skills list --status pending
pando skills approve verify-the-build-before-reporting-done
pando skills reject some-skill-id
Prompt variants
Put an alternative wording of a prompt section in .pando/prompts/variants/<section>/<name>.md.tpl. Pando uses one variant per session, tracks the scores and gradually prefers the one that works better. Requires enabled = true; templates.enabled is the kill switch.
Context trimmer
Experimental and off by default: an extra model call on every new session that filters the tools shown to the model. Web UI: Context trimmer and Trimmer minimum confidence (0.70). Config block: [evaluator.contextTrimmer].
Correction patterns
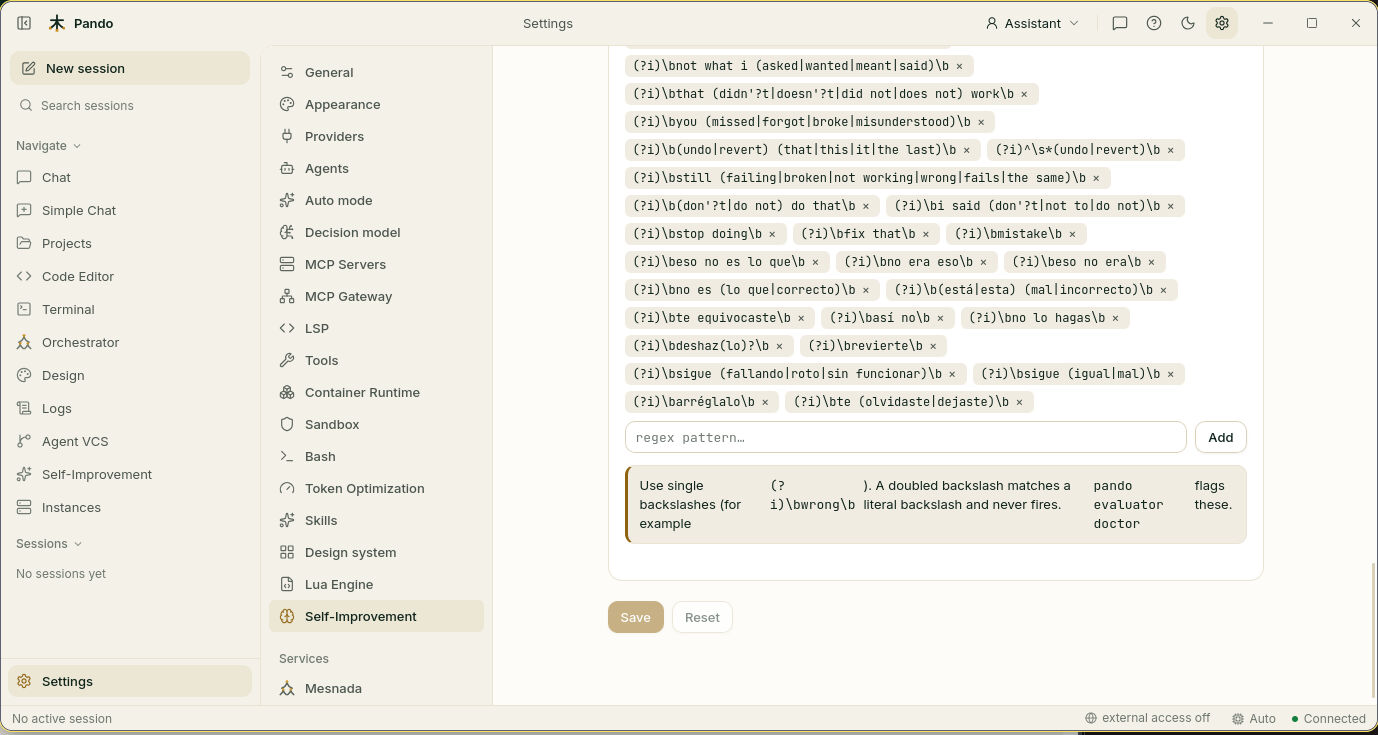
Regular expressions that mark a user message as a correction. Use single backslashes, for example (?i)\bwrong\b. A doubled backslash matches a literal backslash and never fires; pando evaluator doctor flags those.
Commands
| Command | What it does |
|---|---|
/feedback good · /feedback bad | Override the score of the current session |
/evaluate [session-id] | Score a session from the chat (defaults to the current one) |
pando evaluator doctor | Say whether the loop is working and why not |
pando evaluate <session-id> | Score one session |
pando evaluate --all --limit 20 | Score sessions that have no score yet. Add --judge to also run the judge |
pando skills list|approve|reject | Review learned skills |